Teams that run customer service in several countries often start a rollout with the sentence "we'll copy what works in the home market and translate it". Translation is the easy part. What breaks is everything the home-market setup assumed without saying: one catalogue, one legal entity, one set of service hours, one person who can approve a change.
This guide covers the rollout decisions that come before language: how to sequence markets, what a small-market pilot has to prove, which policies are global and which are local, and how to keep brand, country and channel identities from blurring. It complements the existing guide to scaling multilingual support, which covers the language operations themselves, and the operating model, which covers who owns the system day to day.
Where this comes from. The guide draws on four conversations Typewise held in 2026 with organisations running or piloting customer-service AI across markets: a pilot review with an outsourced service provider that handles several brands in several countries, a planning discussion with a consumer-goods manufacturer rolling its chat agent out to country subsidiaries, a pilot review with a multinational's service hubs, and a monthly review my colleague held with a retailer's chat team about translation. I was in three. Observations are anonymised and marked as reported; the sequencing, the global-versus-local split and the checklist are our recommendation.
Start with the structure, not the language
Write down, per market, the things that differ. The list is usually longer than expected:
- Catalogue and availability. Products, prices and links differ by country. An agent that serves a home-market link to a customer in another market is wrong even when the sentence is perfect. Country selection has to be enforced in the data lookup, not left to the model.
- Legal entity and identity. Sender mailbox, signature, phone number, legal footer and the entity named in a reply can differ by country and by brand. Where an outsourced team serves several brands across several countries, each combination needs to stay distinct in what the customer sees and in the reporting. The outsourced provider told us each brand-country mailbox carries its own sender identity and legal footer, and that the brands need reply rates reported separately for marketplace orders and their own shops, which is why that classification could not regress.
- Channel mix. A marketplace order and an own-shop order may have different service obligations and different reporting expectations. Classification by channel is a requirement, not a nicety.
- Entitlements. Warranty terms, return windows, delivery options and local consumer rights differ. These belong in a per-market policy, enforced where the data lives.
- Service hours and staffing. The handoff design for one time zone does not transfer. See handoff ownership for the after-hours decisions.
- Approval and consultation. Some countries require consultation with employee representatives before a tool that measures work is introduced; others do not. Lead times for that consultation can change the whole sequence.
Only once this table exists can you decide what "copy and adapt" actually means for each market.
Sequence markets by what each one proves
A rollout order based on size alone is tempting: start with the biggest market, get the biggest result. In practice the first market should be the one that teaches you the most at the lowest risk.
A small-market pilot is useful because it surfaces cross-system problems before volume arrives: tickets that bypass the new routing, parallel tickets created by two systems, a data feed that was uploaded by hand for the pilot and cannot be uploaded by hand at scale. Those are the things to fix before the large market, and they are invisible in a demo. The provider's lead told us the small first market had been the right place to start, and that the daily manual upload of a data file, workable in the pilot, could not scale. Tickets that bypass the new routing and parallel tickets created by two systems are the test scenarios we recommend running there, before the large market.
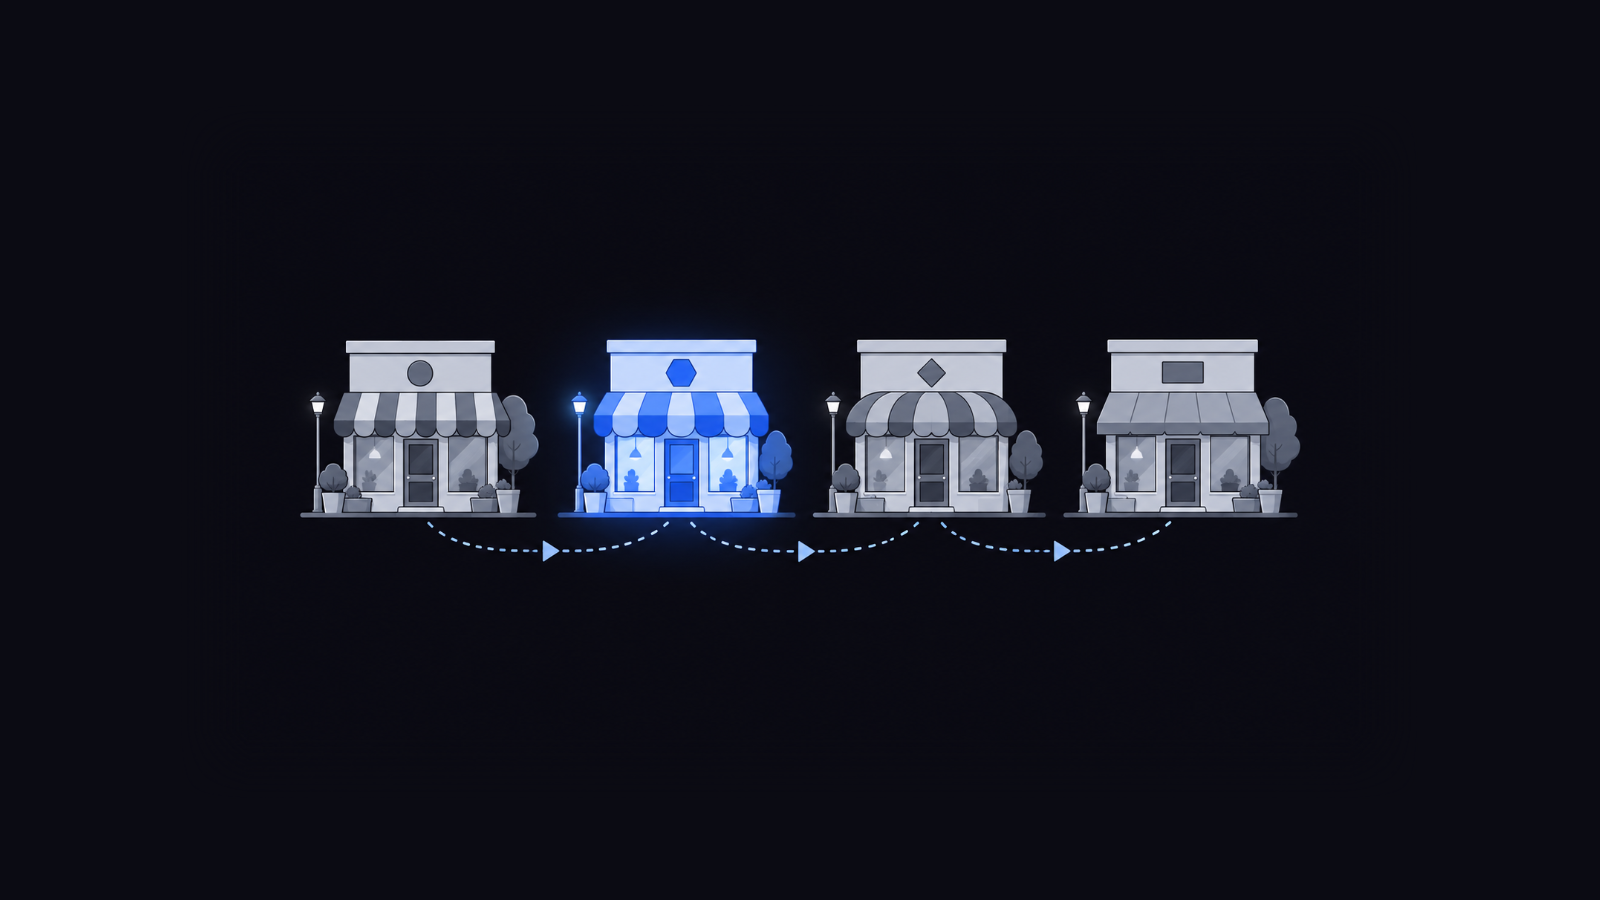
A second mailbox or second market test is the step that is easiest to skip and should not be. The first market proves the workflow; the second proves that the configuration can be duplicated without carrying the first market's assumptions with it. Expect the second to expose stale links, wrong-country lookups and access that was never enabled for the new team. The manufacturer's e-commerce lead described her plan as copying the home-market chat one to one per country, with each country's store view enforced in the product lookup before the other countries were released. Stale links to products no longer available and wrong-country lookups are the checks we recommend running on every copy before release.
Then sequence the rest by a combination of demand (where are customers already writing from?), readiness (is the local data in place?), and consultation lead time. A market where approval takes months can be started earlier administratively and launched later technically.
Two cautions. First, do not count countries as independent proof. A workflow that works in three markets of one organisation has been tested in one organisation. Second, scale at the pace of the business owner. A rollout led by someone for whom this is a side project is more likely to hold together when it is staged than when every market is launched at once. The same e-commerce lead was clear that she could not run everything at once, because the rollout was not her main job; replicating the chat came first and email expansion later.
Separate global from local policy
Decide, explicitly and in writing, which rules are the same everywhere and which a market may set. A reasonable default split:
| Global (set once, enforced everywhere) | Local (owned per market) |
|---|---|
| Data handling, retention and what the AI may never see | Language of reply and customer-language policy |
| Which actions are execute, draft or recommend | Return windows, warranty terms, delivery options |
| Approval thresholds and who may change them | Service hours and after-hours behaviour |
| Brand tone principles | Local phrasing, glossary terms, legal footers |
| Evaluation method and quality bar | Test cases drawn from local tickets |
| Incident process | Local escalation contacts |
The split matters most for three things.
Customer-language policy. Decide whether customers are answered in their own language or in a company language before you evaluate any translation feature; the glossary and quality controls you need depend on that answer. The retailer's chat team lead told my colleague they had not decided whether a customer writing in, say, Bulgarian should be answered in Bulgarian or in English, and that looking at a glossary made no sense until they had. The policy also shapes hiring: the same team's interest in reliable translation came partly from a plan to hire English-only agents who would still answer German tickets. A team that answers local-language tickets with staff who do not speak the language depends on translation reliability in a way the home market never did.
Tool consistency. If an approved translation experience changes, people quietly move to whatever tool is closest, and the team loses sight of where customer text is going. That retailer had lost track of how agents translated after the approved tool moved from the service desk to a browser plug-in; agents drifted to other tools the team could not see. Choose an official approach per market and make it the easy one.
Decision rights. A locally successful rollout can stall when the decision moves to a global or newly acquired parent. Agree in advance which choices stay local during a transition.
Pilot results can overturn the plan
A multi-country pilot can find that the feature expected to matter most is not the one that does. A writing assistant valued in one hub can add checking effort in another, while translation embedded in the workflow turns out to be the clearly validated need for multilingual teams. That is what the multinational's pilot review concluded: translation inside the agent workflow was the clearly validated need for its multilingual hubs, writing assistance was mixed and in some teams added effort because suggestions had to be checked or reversed, and the programme lead said that before the pilot he would have bet on writing assistance. Treat that as a success of the pilot, not a failure of the plan: separate the business capability you want (answer customers in their language, at the hub's speed) from the specific tool, and let the evidence decide which capability to scale first.
Then take the global decision as a decision. Quietly extending a pilot in one or two countries creates two problems later: those teams become attached to a tool that may not be the global choice, and every other country asks why they were left out. The same review did this: the enterprise architect preferred consolidated platforms to several small ones, the programme lead did not want two countries attached to a tool that might not be the global choice while others asked why they were left out, and they paused with a date to check in. Decide, communicate, and if the answer is "pause", pause cleanly with a date to revisit.
Keep a transition-period automation narrow
When a market is mid-migration between platforms, resist the broad rollout. Finish the narrow automation that is already delivering (one product line's email handling, say) and keep it separate from the platform project. Make sure conversation history can travel to whatever system comes next; a rollout that strands history in a retired tool costs more than it saved.
Rollout checklist per market
- [ ] Per-market differences table completed: catalogue, entity, channels, entitlements, hours, consultation.
- [ ] Country selection enforced in data lookups; stale links and unavailable products checked.
- [ ] Sender identity, signature and legal footer correct for every brand-country-channel combination.
- [ ] Reporting classifies by channel and market.
- [ ] Data feeds automated before volume; no manual daily uploads.
- [ ] Customer-language policy decided; glossary owner named.
- [ ] Local policy owner and local escalation contact named.
- [ ] Consultation and approval lead times in the plan.
- [ ] Second-market duplication test passed before the large market.
- [ ] Global decision and communication plan agreed before the pilot ends.
Limits
This guide assumes a shared platform with per-market configuration. Organisations whose markets run entirely different service systems face a migration question first, which is outside this scope. It also does not cover legal requirements in any jurisdiction; consultation obligations and consumer rights differ and need local advice. Finally, the staged approach trades speed for safety; where demand from a market is urgent, start the administrative steps early rather than skipping the second-market test.
Related reading
- Scaling multilingual support efficiently: the language operations once the structure is right.
- Who owns customer-service AI after the pilot?: the roles that need a local and a global owner.
- Is your customer data ready for an AI agent?: the per-market data checks.
FAQ
Should we start with the largest market?
Not necessarily. Start where the pilot teaches the most at the lowest risk, then run a second-market duplication test before the large market. Cross-system routing and data-feed problems show up there, not in the demo.
Which policies must be global?
Data handling, the action rights the AI holds, approval thresholds, the evaluation bar and the incident process. Language policy, entitlements, hours, local phrasing and escalation contacts are owned per market.
What if the pilot shows a different feature matters than we planned?
Treat it as the pilot working. Separate the business capability from the tool, prioritise the validated need, and take an explicit global decision rather than quietly extending the pilot in a few countries.